Documenting an existing database is one of the best uses of Mermaid ER diagrams. Here's how to translate SQL into erDiagram syntax — and how to let AI do it in seconds.
Starting point: SQL
CREATE TABLE authors (
  id SERIAL PRIMARY KEY,
  name TEXT NOT NULL
);
CREATE TABLE books (
  id SERIAL PRIMARY KEY,
  author_id INT NOT NULL REFERENCES authors(id),
  isbn TEXT UNIQUE,
  title TEXT NOT NULL
);
The Mermaid version
erDiagram
    AUTHOR ||--o{ BOOK : writes
    AUTHOR {
      int id PK
      text name
    }
    BOOK {
      int id PK
      int author_id FK
      text isbn UK
      text title
    }
Mapping rules
| SQL | Mermaid |
|---|---|
| PRIMARY KEY | PK |
| REFERENCES / FOREIGN KEY | FK + a relationship line |
| UNIQUE | UK |
| NOT NULL foreign key | || on the parent side (exactly one) |
| Nullable foreign key | |o on the parent side (zero or one) |
| Join table with two FKs | Two one-to-many relationships |
Let AI convert it
In the editor, open AI → Generate, paste your SQL and ask: "Convert this schema into a Mermaid ER diagram with keys and relationships." Review the result and use Edit to tweak names or remove noise like audit columns.
A join table is its own entity
The authors and books example above is sql to mermaid for a single foreign key. A many-to-many relationship in SQL is almost never a single line. It is a third table. If you skip that table, the diagram hides the columns you came here to document.
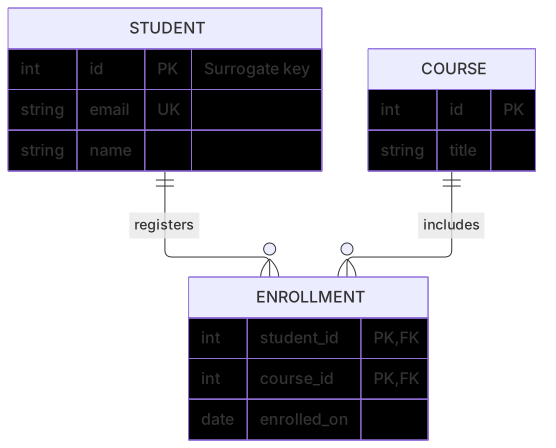
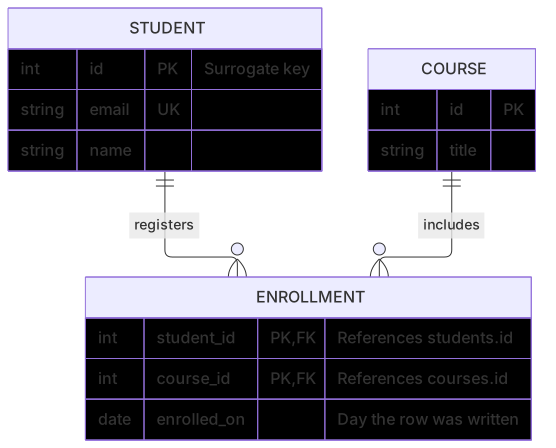
Take students, courses, and enrollments. A student can take many courses. A course has many students. The database stores that with enrollments, whose primary key is the pair of foreign keys. Those two facts are two relationships, both one-to-many, both pointing at the join table.
erDiagram
    STUDENT ||--o{ ENROLLMENT : registers
    COURSE ||--o{ ENROLLMENT : includes
    STUDENT {
        int id PK "Surrogate key"
        string email UK
        string name
    }
    COURSE {
        int id PK
        string title
    }
    ENROLLMENT {
        int student_id PK, FK
        int course_id PK, FK
        date enrolled_on
}Read STUDENT ||--o{ ENROLLMENT from the markers outward. The marker touching STUDENT is ||, exactly one. The marker touching ENROLLMENT is o{, zero or more. One student has zero or more enrollment rows. One enrollment row has exactly one student. The same reading on the course line says one course has many enrollment rows, and each row has exactly one course. Together those lines are the many-to-many. There is no direct STUDENT-to-COURSE line, because there is no foreign key that skips the join.
PK, FK on student_id is doing two jobs. It is part of the primary key, and it references students.id. The ER reference lists the key markers. Use UK for a unique column that isn't the primary key, as on email. Don't mark a column FK unless the SQL has a real reference. A column named course_id with no constraint is a guess, and the guess belongs in a comment, not in a crow's foot.
When a generator draws STUDENT }o--o{ COURSE and deletes ENROLLMENT, it simplified the schema. Put the entity back. The prompt guide has the instruction to keep the join table. The picture is only finished when every CREATE TABLE you care about is an entity.
Nullable foreign keys
|| means exactly one. |o on the left, and o| on the right, mean zero or one. That is the difference between NOT NULL and a foreign key that may be null.
If books.author_id is NOT NULL, every book has an author. The marker next to AUTHOR is exactly one: AUTHOR ||--o{ BOOK. The marker next to BOOK stays o{ if one author has many books. The short example at the top of this page is that shape.
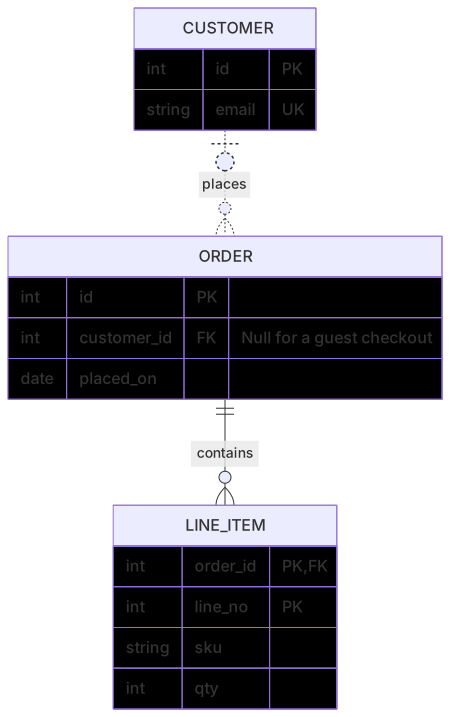
If orders.customer_id may be null, a guest checkout has no customer row. The marker next to CUSTOMER has to allow zero. Use |o on the left:
erDiagram
    CUSTOMER |o..o{ ORDER : places
    ORDER ||--o{ LINE_ITEM : contains
    CUSTOMER {
        int id PK
        string email UK
    }
    ORDER {
        int id PK
        int customer_id FK "Null for a guest checkout"
        date placed_on
    }
    LINE_ITEM {
        int order_id PK, FK
        int line_no PK
        string sku
        int qty
}|o is zero or one customer. o{ is zero or more orders. A required customer would be || in that same position. People swap them when they read the line like English instead of like markers. The marker is glued to the entity it counts. Cover the rest of the line with your hand and read one end at a time.
The right-hand twins are mirrored. Zero or one on the right is o|, not |o. Zero or more on the right is o{. One or more on the right is |{. On the left, one or more is }| and zero or more is }o. You rarely need one-or-more. o{ matches the usual foreign key, where the parent may have no children yet. Use |{ only when the schema or a constraint really forbids an empty parent. An order with zero line items is a valid draft, so the line-item end in the diagram is o{.
Nullable is not the same thing as optional participation in a join table. enrollments.student_id is part of a primary key, so it cannot be null. Don't draw |o on a column the database rejects. The nullability comes from the SQL, not from how optional the product feels.
Identifying and non-identifying lines
The hyphens between the markers are a second decision. -- is a solid line. In this diagram type it means an identifying relationship: the child's primary key includes the parent's key. .. is a dashed line. It means a non-identifying relationship: the foreign key is an ordinary column, and the child has its own primary key.
Look at the two diagrams above. ENROLLMENT uses student_id and course_id as its primary key, so both relationships are solid --. A line item's primary key includes order_id, so ORDER ||--o{ LINE_ITEM is solid too. ORDER.customer_id is a foreign key and it is not part of ORDER's primary key (id is). That relationship is dashed: |o..o{. The dots are the whole difference. The markers on the ends still say zero-or-one and zero-or-more.
A book with its own id and a separate author_id is the non-identifying case, even when author_id is NOT NULL. Required and identifying are different axes. Required is || versus |o. Identifying is -- versus ... You can have a required non-identifying key: AUTHOR ||..o{ BOOK when every book has an author and books.id is still the primary key. You can have an identifying key that is required, which is the enrollment case, because a primary-key column is never null.
If you are unsure, look at the child's primary key in the CREATE TABLE. If the foreign key column appears in that key, draw --. If the child has a surrogate id and the foreign key is only a constraint, draw ... The syntax guide won't catch a solid line on a non-identifying key. The parser is happy either way. The reader is the one you mislead.
Comments on an attribute
A comment sits in double quotes after the type, the name, and any keys. It renders on the entity when there's room, and it is the right place for a fact the column name doesn't carry.
int customer_id FK "Null for a guest checkout" says the null is a product rule, not a forgotten constraint. int id PK "Surrogate key" tells the next reader that the id is not a natural key. string email UK doesn't need a comment if the name and the UK already say "unique email." Comment the column that will be misread. Skip the column that won't.
Quotes around the comment follow the same rules as other labels. A comment with a parenthesis is fine inside the quotes. A comment with a raw double quote needs #quot; or a rephrase. Keep comments short. A paragraph in the quote wraps into an unreadable box. Put the policy in the page under the diagram, and let the quote be the reminder.
Attribute order should follow the table: primary key, then foreign keys, then the columns a reader uses to recognize a row. Mermaid doesn't sort them for you. The order in the braces is the order in the picture.
Check the diagram against the SQL
Walk each foreign key once. For enrollments.student_id you should be able to point at one relationship, one FK mark, and a cardinality you can defend from NOT NULL and from the primary key. Then do course_id. Then stop. Extra relationships are inventions. Missing ones are the join you forgot.
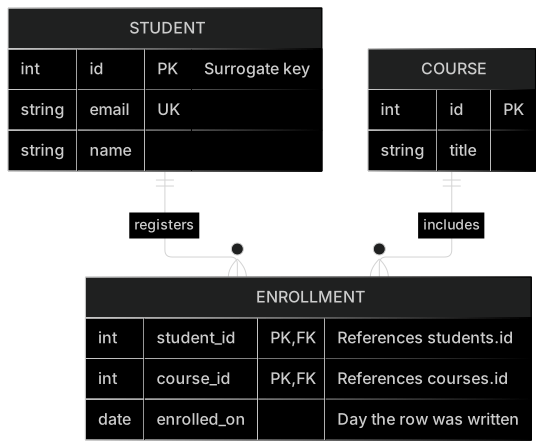
This three-table file is a valid erDiagram you can paste and extend. It is the enrollment model, with comments and a composite key:
erDiagram
    STUDENT ||--o{ ENROLLMENT : registers
    COURSE ||--o{ ENROLLMENT : includes
    STUDENT {
        int id PK "Surrogate key"
        string email UK
        string name
    }
    COURSE {
        int id PK
        string title
    }
    ENROLLMENT {
        int student_id PK, FK "References students.id"
        int course_id PK, FK "References courses.id"
        date enrolled_on "Day the row was written"
}The order diagram higher up is the other three-table case: a nullable, non-identifying customer, and an identifying line item. Use that one when the SQL has a guest column. Use this one when the SQL has a join table. Using both patterns in one chart is normal. A schema can have a nullable owner and a composite key on a different table. Draw each key from its own column, not from the mood of the feature.
Names in the diagram can be uppercase singular even when the tables are plural. students becomes STUDENT if you stay consistent and the comment still names the real table. Don't rename email to address because it sounds nicer. The point of going from SQL to a diagram is that a reader can find the column.
When the file parses and a cardinality still feels wrong, trust the CREATE TABLE over the picture. Change the marker, render again, and only then paste the diagram into a README. The editor is the fastest place to flip |o to || and see the crow's foot move.
What the diagram is allowed to rename
Table names can become singular and uppercase. Column names should not become friendlier words. created_at stays created_at so a reader can search the migration. If a column is a foreign key, the relationship line has to name the same column the REFERENCES clause names. A line that says "owns" while the SQL says author_id forces the next person to guess.
Composite primary keys need both columns in the entity and a relationship that does not pretend one of them is optional. If the SQL says PRIMARY KEY (order_id, product_id), the diagram's identifying relationship is ||--|{ or the equivalent you can defend from that constraint, not a guess from the UI. Leave out indexes that are not keys. A unique email is a key worth drawing. A plain index on created_at is not an entity relationship.
When AI drafts the chart, diff it against the CREATE TABLE list before you trust the crows feet. Missing tables are the common failure, not extra ones. The ER diagram page has the marker list, and the editor is where you flip a marker and see the foot change.